Apprentice
Teacher corrections live in CockroachDB. Accuracy still falls.
An analyst agent writes SQL against a tiny company sales database. House rules (how this company defines revenue, quarters, and live orders) are not in the schema — they live in CockroachDB memory after a teacher corrects the agent. Ask the same exam question cold, then with memory. Then see what happens when you scale that to fifty questions.
Live · CockroachDB memory + Bedrock SQL + toy warehouse
Same question, two brains
Pick an exam question, ask with an empty memory, then ask again with teacher corrections recalled from CockroachDB. Watch whether retrieved rules appear and whether the graded answer flips. The ★ recommended item is the cleanest contrast; Step 2 runs once on page load for that item so you are not staring at a blank panel.
Ask the agent a question below. Once with an empty memory, once with memory — and watch the answer change.
Pick an exam question
Any of the fifty is fair game. ★ recommended gives the cleanest cold→memory flip; other items may grade wrong, error (SQL that will not run), or even correct cold — that is the exam, not a scripted tour.
Loading question…
Ask without memory
Empty brain — no CockroachDB rules in the prompt. Expect a wrong or incomplete answer.
Ask with memory
Same question, but rules are recalled from CockroachDB first. Compare retrieved rules and the grade.
What’s the data? (warehouse + house rules)
Two stores, on purpose. CockroachDB holds the agent’s memory (teacher corrections as semantic rules). A separate SQLite prop warehouse holds the fake company’s sales data the SQL runs against — about six orders, seeded so “calendar quarter” and “this company’s fiscal quarter” disagree.
Tables the agent can query
House rules that are not in the schema (they arrive via memory)
revenue= line amounts minus refunds; skip cancelled and soft-deleted orders- This company’s fiscal year starts 1 February — so “fiscal Q2 2026” is May–July, not April–June
- Region rolls up through the customer, not the product
“Frozen label” means: before any agent ran, I computed the correct row for each exam question and checked it into git. Live answers are graded against that — not against a judge’s gut feel.
Live path: recall from CockroachDB → SQL from Bedrock → execute on the prop warehouse
→ grade vs labels at b043aea. Epoch HLCs for the curve below are past the
75-minute GC window, so that chart is a published snapshot — the try widget uses
current memory. Optional
3‑min walkthrough.
That worked. At fifty questions it stops working — here is the honest version.
At exam scale — the recorded curve
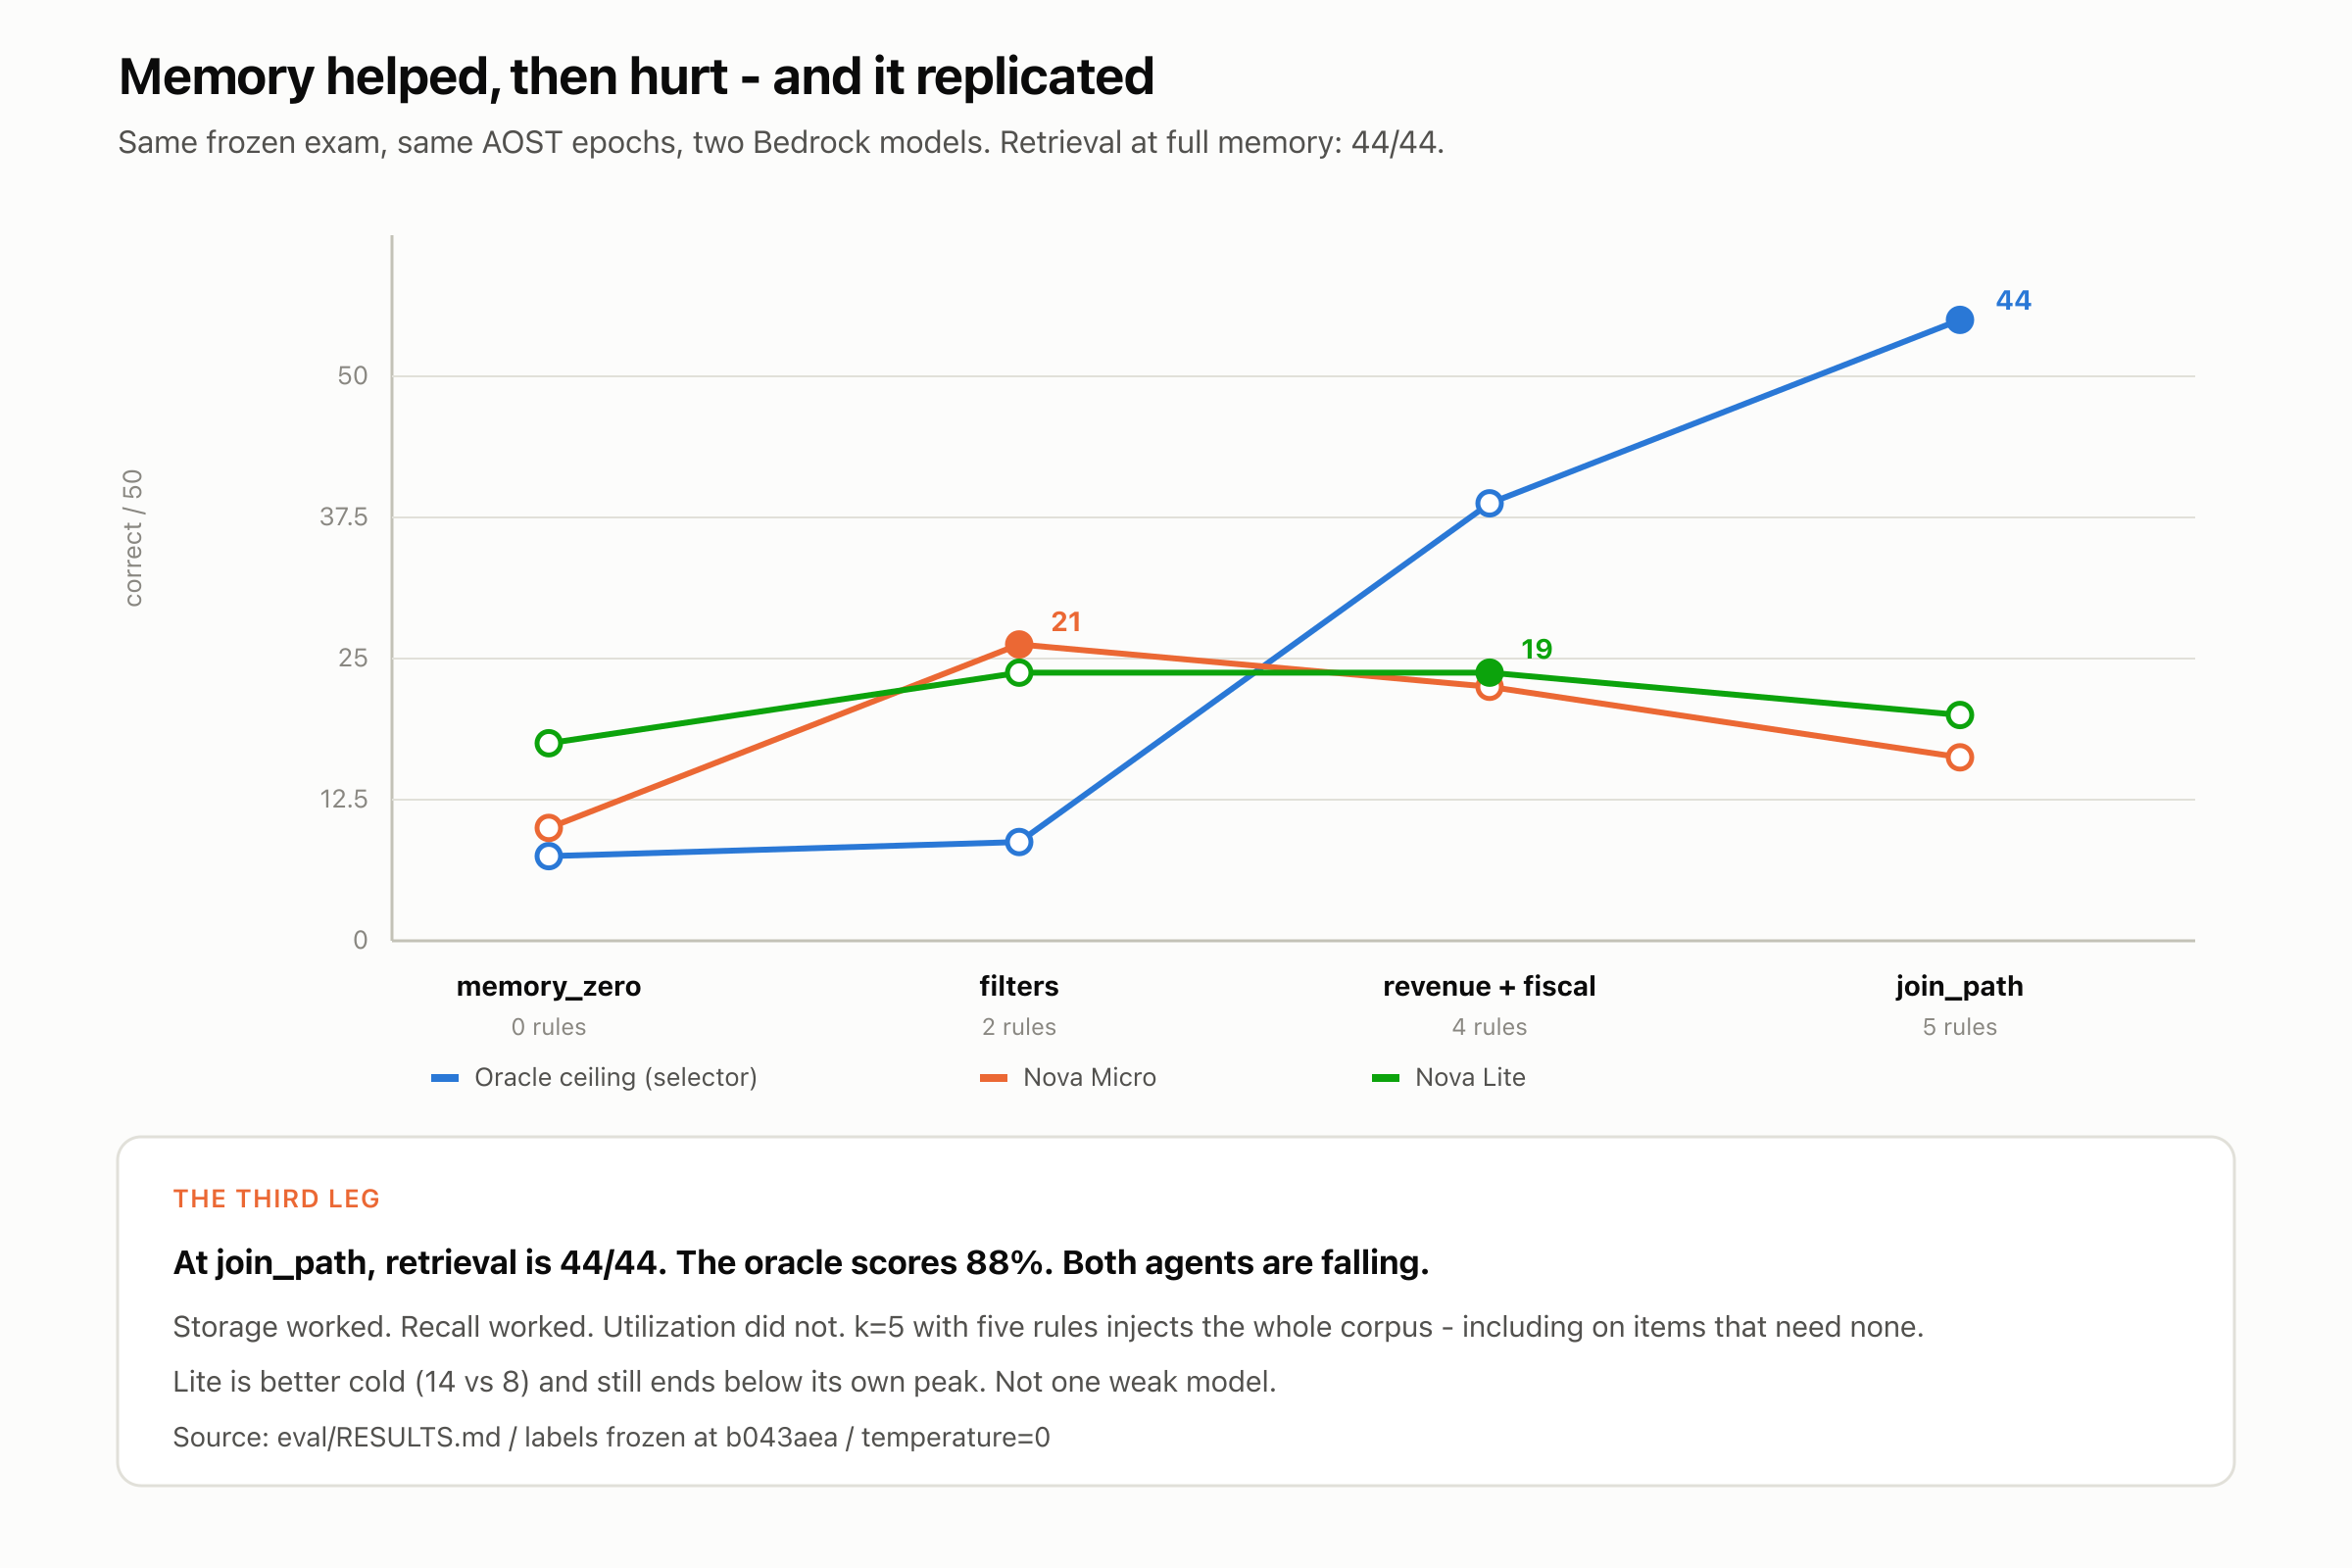
Scores by education epoch
| Epoch | Rules | Oracle | Nova Micro | Nova Lite |
|---|---|---|---|---|
memory_zero |
0 | 6/50 | 8/50 | 14/50 |
filters |
2 | 7/50 | 21/50 | 19/50 |
revenue_and_fiscal |
4 | 31/50 | 18/50 | 19/50 |
join_path |
5 | 44/50 | 13/50 | 16/50 |
Bold cells = that column’s peak. Both agents peak before full memory.
Why accuracy fell
The drop is not “memory failed to store.” At full memory, retrieval of the rules the gold SQL needed was 44/44. Storage and recall worked. Utilization did not: the model over-applies house rules on questions that should stay untouched.
Over-application is real and replicated; it is not monotonic with rule count.
Both models end below their own unaffected peak — Micro 5/6 → 3/6,
Lite 6/6 → 4/6. Lite’s worst cell (3/6) is at filters (two rules), not
at full memory. Micro bottoms at 2/6 mid-curriculum.
k=5 was fixed before the run. With five live rules, retrieval returns
the whole corpus and ranks nothing. That describes the prompt. It does not fully
explain the unaffected column.
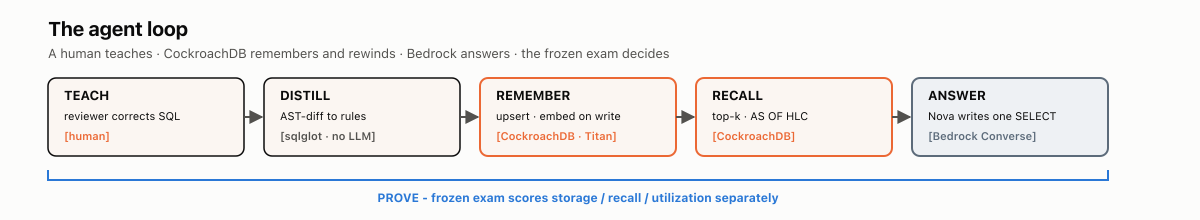
How the agent is wired
Separate beat from “why it fell.” This is the teach → remember → answer loop that produces the memory the try widget and the exam both use.
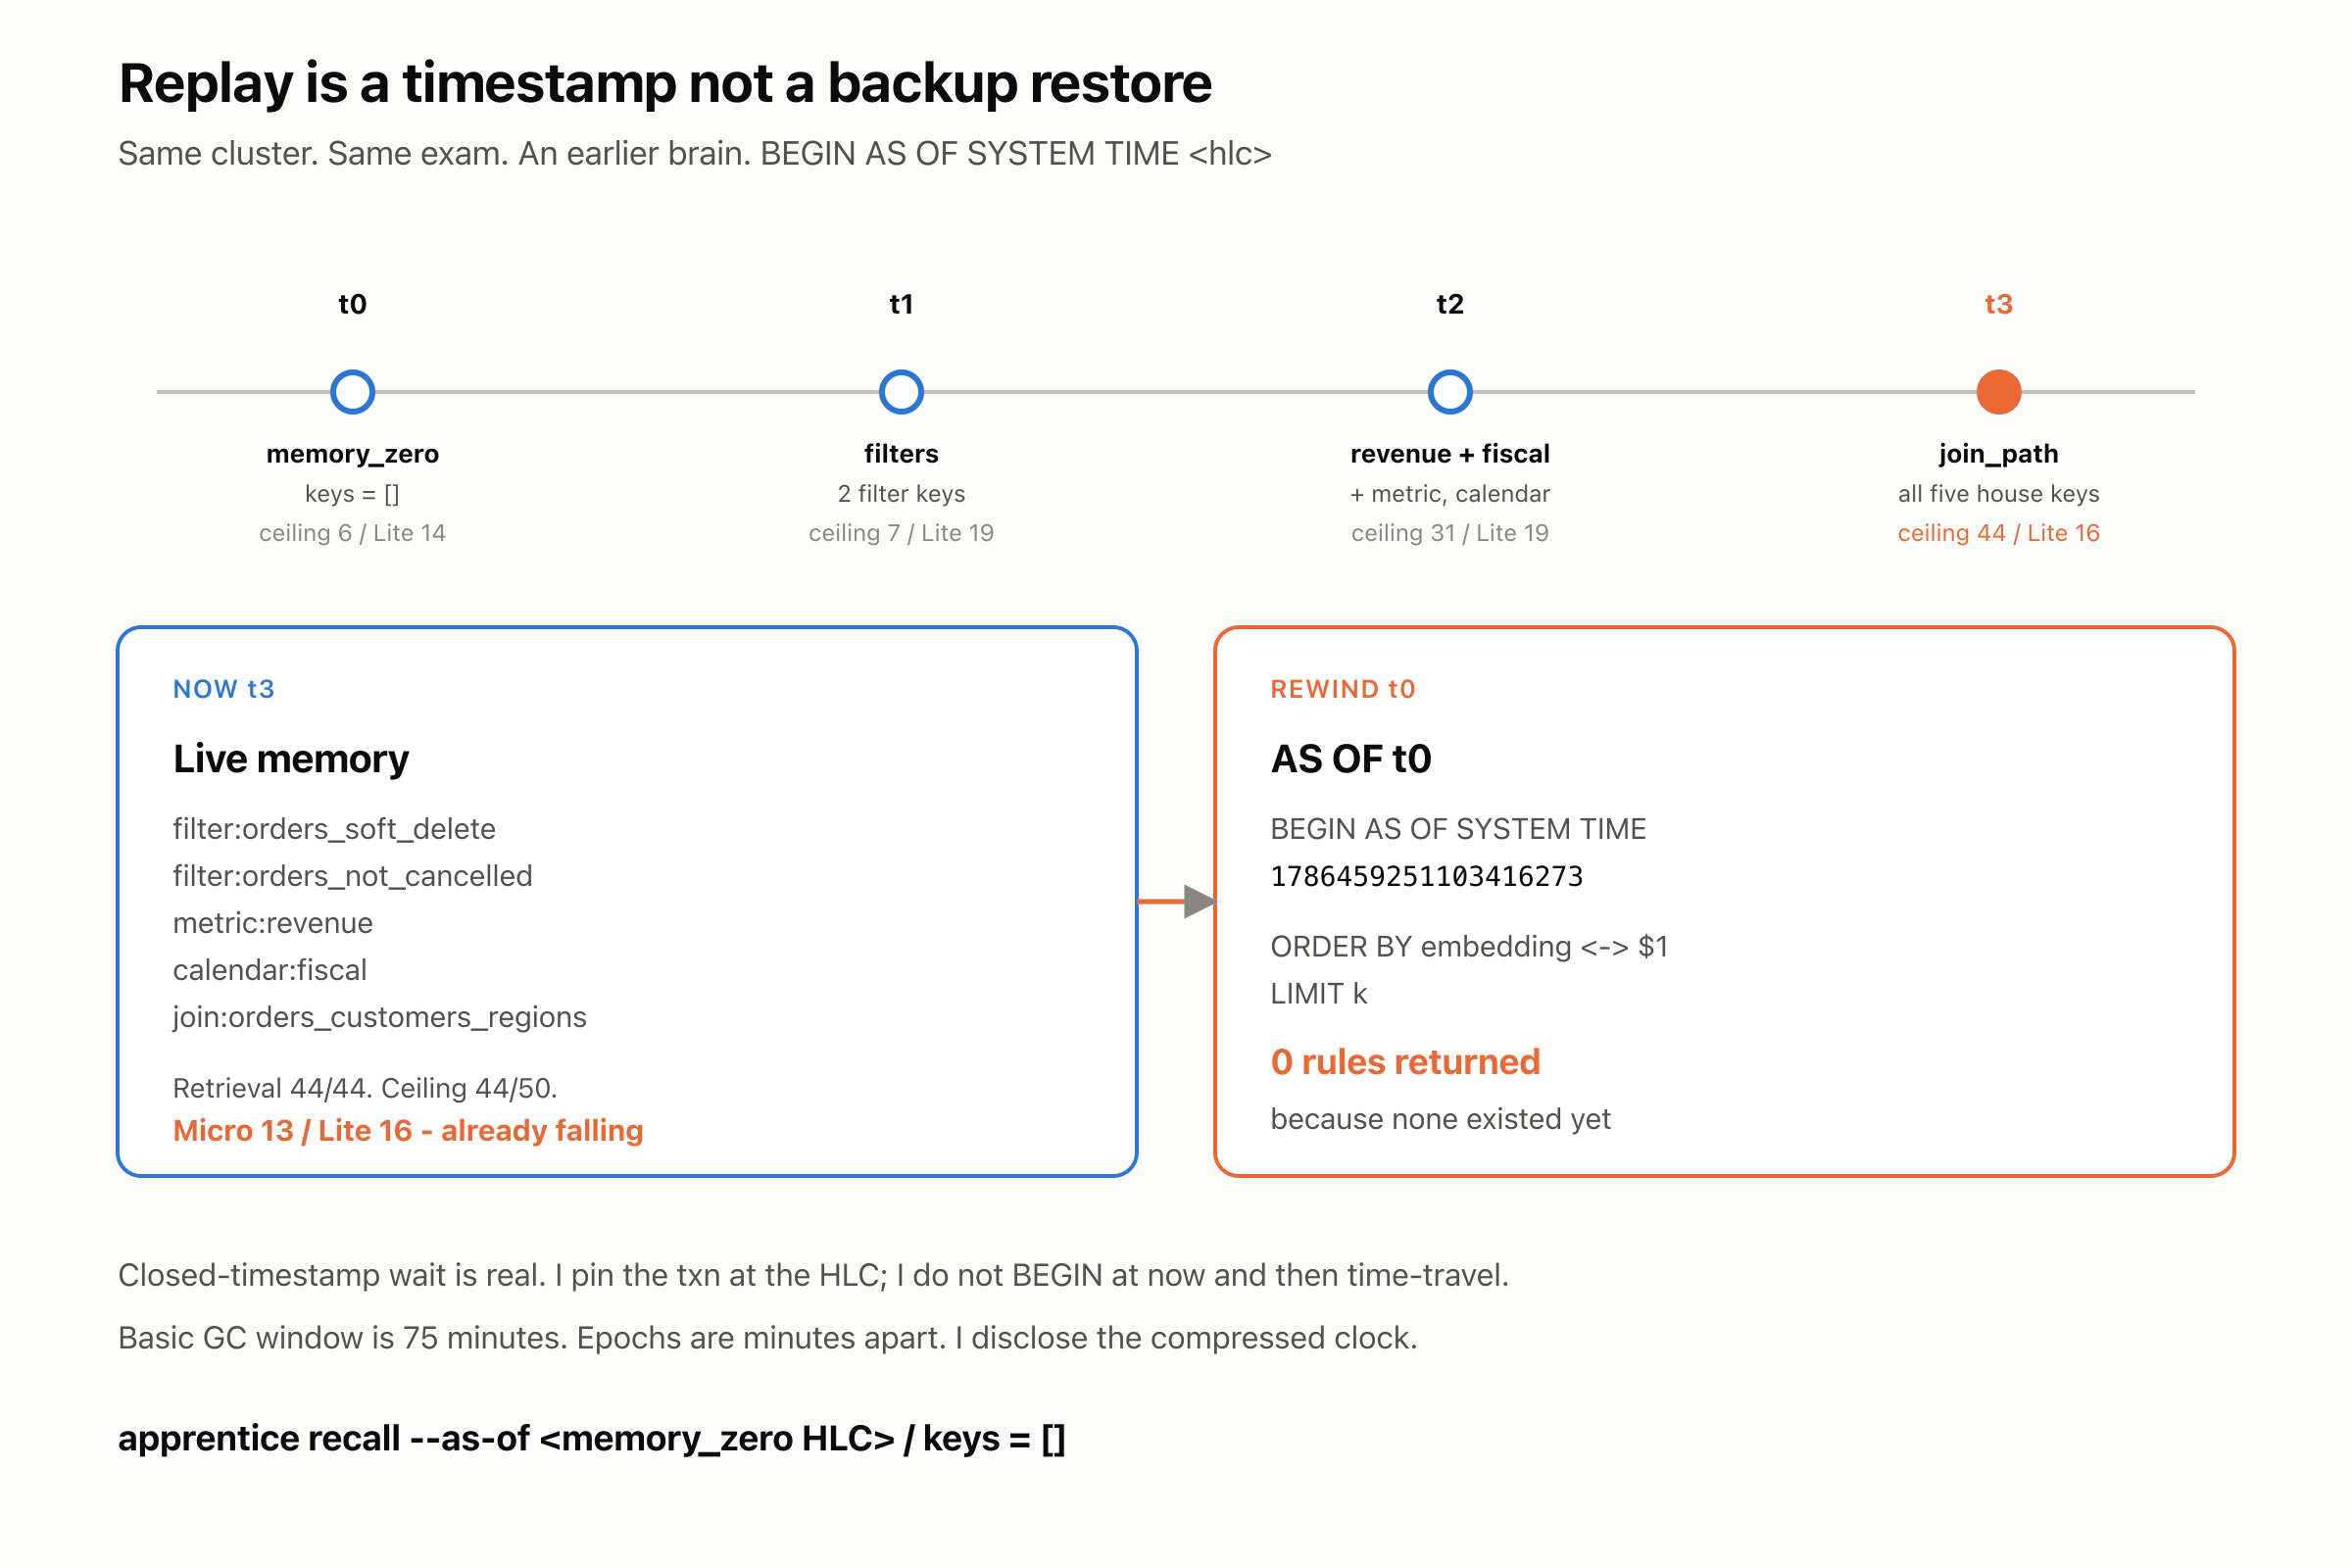
How education epochs rewind
The curve above is four snapshots of the same CockroachDB cluster at four
Hybrid Logical Clock timestamps — not four restored backups. After teaching, I score
the exam AS OF each education epoch (memory_zero →
join_path).
Reproduce the freeze (no cluster)
git clone https://github.com/prasadt1/apprentice-crdb.git
cd apprentice-crdb
python3.11 -m venv .venv && source .venv/bin/activate
pip install -e ".[dev]"
pytest -q
python eval/run_exam.py verify
This page is the functional demo URL. The CLI is the product.
Live memory needs APPRENTICE_CRDB_DSN on the Lambda behind the try widget.